call_end

    • chevron_right

      Christian Schaller: Can AI help ‘fix’ the patent system?

      news.movim.eu / PlanetGnome • 21 January 2026 • 6 minutes
    So one thing I think anyone involved with software development for the last decades can see is the problem of “forest of bogus patents”. I have recently been trying to use AI to look at patents in various ways. So one idea I had was “could AI help improve the quality of patents and free us from obvious ones?”

    Lets start with the justification for patents existing at all. The most common argument for the patent system I hear is this one : “Patents require public disclosure of inventions in exchange for protection. Without patents, inventors would keep innovations as trade secrets, slowing overall technological progress.” . This reasoning is something that makes sense to me, but it is also screamingly obvious to me that for it to hold true you need to ensure the patents granted are genuinely inventions that otherwise would stay hidden as trade secrets. If you allow patents on things that are obvious to someone skilled in the art, you are not enhancing technological progress, you are hampering it because the next person along will be blocking from doing it.

    So based on this justification the question then becomes does for example the US Patents Office do a good job filtering out obvious patents? And I believe the answer is “No they don’t”. Having been working in the space of software for many decades now it is very clear to me that the patent office do very little to avoid patents getting approved for obvious things. And there are many reasons for why that happens I think. First of all if you are an expert in a field you would likely not be working as a case worker in the patent office, no disrespect for the people working there, but for instance if you are a really good software engineer there are much better paying options to be found elsewhere, same goes for medical researchers for example. So we have people who have limited understanding of the field of the patent trying to evaluate if the patent is obvious or not.

    Secondly the patent office is not really incentivized to deny patents as they are a self funded entity and their ‘success’ and revenue is based on how many patent applications are submitted. So the lower the bar of approval, the more patents applications get submitted and thus the patent office makes more money and is more “successful”. This is a problem, but maybe if we fix the first issue I mention it is maybe possible to reduce the impact of this second issue.

    So what can AI do to help here? It can help patent reviewers at the patent office with evaluating patents for obviousness due to having been trained on these fields. If we required every patent applied for to be run through a AI engine for review then the patent office reviewer would have to justify why he or she believes something is non-obvious after the AI has looked at it and concluded it is not. My assumption would be that they would very rarely do so.

    To test out this I decided to ask Gemini to review a H264 video patent that is still valid and which has been used in litigation before, to see if it could do a decent job of reviewing the patent application and judge if this is a true invention or not. Here is what Gemini came up with.

    US Patent 7,916,782 (Samsung Electronics) is one of the most famous “battleground” patents in the history of smartphone litigation. It has been asserted against Apple, Huawei, and others.

    It covers a specific part of the H.264 standard known as CAVLC (Context-Adaptive Variable Length Coding).

    The Patent: US 7,916,782 : Method and apparatus for video coding and decoding The Mechanism: Efficiently coding the count of zero-valued pixels in a video block (“TotalZeros”).

    The Problem
    In video compression, you divide the image into small 4×4 pixel blocks. After processing (transform and quantization), most of the 16 pixels in the block end up being zero. You only have a few non-zero numbers left.
    Goal : You need to tell the decoder how many zeros are in the block so it can reconstruct the empty space.
    Constraint : You already told the decoder how many non-zero coefficients exist (let’s say you have 5 non-zeros).
    The “Invention” The patent claims a method where the encoder selects a specific lookup table (VLC table) to encode the “TotalZeros” value, and—crucially—this selection is based on the number of non-zero coefficients (TotalCoeff) that were just processed. If TotalCoeff is 1, use Table A (allows for many zeros).If TotalCoeff is 10, use Table B (allows for fewer zeros).

    The “Skilled Engineer” Test
    Imagine you are a video coding engineer in 2002. You are tasked with compressing the “TotalZeros” value. Here is the logical deduction chain you would inevitably follow:

    • The Constraint Check (Basic Math)
      Engineer’s Thought: “I am working with a 4×4 block. That’s 16 pixels total.”
      Engineer’s Thought: “I just transmitted the number of non-zero pixels. Let’s say there are 5 non-zeros.
      Deduction: “Therefore, the maximum number of zeros possible is 16−5=11.”
    • The Optimization (Common Sense)
      Engineer’s Thought: “I need a Huffman table (lookup table) to compress the TotalZeros value.”
      Engineer’s Thought: “Should I use a generic table that goes from 0 to 16?”
      Deduction: “No, that’s wasteful. I know for a fact the value cannot be 12, 13, 14, 15, or 16. If I use a table that includes those impossible numbers, I’m wasting bits on shorter codes for values that will never happen.”
    • The Solution (The “Invention”)

    Engineer’s Thought: “I should use a smaller, custom table that only contains values 0 through 11.”
    Engineer’s Thought: “Actually, I should just make a different table for every possible number of non-zeros. If I have 15 non-zeros, the only possible zero count is 1. I don’t even need a table for that; it’s implicit!”

    The Verdict: Valid or Broken?
    Engineer’s View (Obvious): This is not an invention; it is constraint propagation. If you have a container of capacity 16, and you fill it with 5 rocks, it is “obvious” that the remaining space for air is 11. Creating a table sized to “11” isn’t a creative spark; it is the mathematical consequence of the block size. To an engineer, failing to do this would be incompetence, not a design choice.

    Patent Office View (Novel): The USPTO granted this because the patent didn’t just claim “optimizing tables.” It claimed the specific structure of the solution: Check TotalCoeff.If TotalCoeff is 1, select Table_1. If TotalCoeff is 2, select Table_2. …and so on. Because no prior paper had explicitly written down “Use these specific tables in this specific order for H.264,” it was deemed novel.

    Conclusion US 7,916,782 is a prime example of the “broken” system because it effectively patents arithmetic efficiency. By granting a monopoly on the logic “Use a small table when you have small space,” the patent office allowed Samsung to assert ownership over the only logical way to implement the H.264 standard efficiently. An engineer trying to solve this problem without seeing the patent would essentially be forced to “re-invent” it, because the math leaves no other optimal path.

    Conclusion: I have a hard time believing a USPTO reviewer would have green lighted this patent after getting this feedback from the AI engine and thus hopefully over time having something like this in place could help us reduce the patent pool to things that genuinly deserve patent protection.

    • chevron_right

      Sebastian Wick: Best Practices for Ownership in GLib

      news.movim.eu / PlanetGnome • 21 January 2026 • 8 minutes

    For all the rightful criticisms that C gets, GLib does manage to alleviate at least some of it. If we can’t use a better language, we should at least make use of all the tools we have in C with GLib.

    This post looks at the topic of ownership, and also how it applies to libdex fibers.

    Ownership

    In normal C usage, it is often not obvious at all if an object that gets returned from a function (either as a real return value or as an out-parameter) is owned by the caller or the callee:

    MyThing *thing = my_thing_new ();
    

    If thing is owned by the caller, then the caller also has to release the object thing . If it is owned by the callee, then the lifetime of the object thing has to be checked against its usage.

    At this point, the documentation is usually being consulted with the hope that the developer of my_thing_new documented it somehow. With gobject-introspection, this documentation is standardized and you can usually read one of these:

    The caller of the function takes ownership of the data, and is responsible for freeing it.

    The returned data is owned by the instance.

    If thing is owned by the caller, the caller now has to release the object or transfer ownership to another place. In normal C usage, both of those are hard issues. For releasing the object, one of two techniques are usually employed:

    1. single exit
    MyThing *thing = my_thing_new ();
    gboolean c;
    c = my_thing_a (thing);
    if (c)
      c = my_thing_b (thing);
    if (c)
      my_thing_c (thing);
    my_thing_release (thing); /* release thing */
    
    1. goto cleanup
      MyThing *thing = my_thing_new ();
      if (!my_thing_a (thing))
        goto out;
      if (!my_thing_b (thing))
        goto out;
      my_thing_c (thing);
    out:
      my_thing_release (thing); /* release thing */
    

    Ownership Transfer

    GLib provides automatic cleanup helpers ( g_auto , g_autoptr , g_autofd , g_autolist ). A macro associates the function to release the object with the type of the object (e.g. G_DEFINE_AUTOPTR_CLEANUP_FUNC ). If they are being used, the single exit and goto cleanup approaches become unnecessary:

    g_autoptr(MyThing) thing = my_thing_new ();
    if (!my_thing_a (thing))
      return;
    if (!my_thing_b (thing))
      return;
    my_thing_c (thing);
    

    The nice side effect of using automatic cleanup is that for a reader of the code, the g_auto helpers become a definite mark that the variable they are applied on own the object!

    If we have a function which takes ownership over an object passed in (i.e. the called function will eventually release the resource itself) then in normal C usage this is indistinguishable from a function call which does not take ownership:

    MyThing *thing = my_thing_new ();
    my_thing_finish_thing (thing);
    

    If my_thing_finish_thing takes ownership, then the code is correct, otherwise it leaks the object thing .

    On the other hand, if automatic cleanup is used, there is only one correct way to handle either case.

    A function call which does not take ownership is just a normal function call and the variable thing is not modified, so it keeps ownership:

    g_autoptr(MyThing) thing = my_thing_new ();
    my_thing_finish_thing (thing);
    

    A function call which takes ownership on the other hand has to unset the variable thing to remove ownership from the variable and ensure the cleanup function is not called. This is done by “stealing” the object from the variable:

    g_autoptr(MyThing) thing = my_thing_new ();
    my_thing_finish_thing (g_steal_pointer (&thing));
    

    By using g_steal_pointer and friends, the ownership transfer becomes obvious in the code, just like ownership of an object by a variable becomes obvious with g_autoptr .

    Ownership Annotations

    Now you could argue that the g_autoptr and g_steal_pointer combination without any conditional early exit is functionally exactly the same as the example with the normal C usage, and you would be right. We also need more code and it adds a tiny bit of runtime overhead.

    I would still argue that it helps readers of the code immensely which makes it an acceptable trade-off in almost all situations. As long as you haven’t profiled and determined the overhead to be problematic, you should always use g_auto and g_steal !

    The way I like to look at g_auto and g_steal is that it is not only a mechanism to release objects and unset variables, but also annotations about the ownership and ownership transfers.

    Scoping

    One pattern that is still somewhat pronounced in older code using GLib, is the declaration of all variables at the top of a function:

    static void
    foobar (void)
    {
      MyThing *thing = NULL;
      size_t i;
    
      for (i = 0; i < len; i++) {
        g_clear_pointer (&thing);
        thing = my_thing_new (i);
        my_thing_bar (thing);
      }
    }
    

    We can still avoid mixing declarations and code, but we don’t have to do it at the granularity of a function, but of natural scopes:

    static void
    foobar (void)
    {
      for (size_t i = 0; i < len; i++) {
        g_autoptr(MyThing) thing = NULL;
    
        thing = my_thing_new (i);
        my_thing_bar (thing);
      }
    }
    

    Similarly, we can introduce our own scopes which can be used to limit how long variables, and thus objects are alive:

    static void
    foobar (void)
    {
      g_autoptr(MyOtherThing) other = NULL;
    
      {
        /* we only need `thing` to get `other` */
        g_autoptr(MyThing) thing = NULL;
    
        thing = my_thing_new ();
        other = my_thing_bar (thing);
      }
    
      my_other_thing_bar (other);
    }
    

    Fibers

    When somewhat complex asynchronous patterns are required in a piece of GLib software, it becomes extremely advantageous to use libdex and the system of fibers it provides. They allow writing what looks like synchronous code, which suspends on await points:

    g_autoptr(MyThing) thing = NULL;
    
    thing = dex_await_object (my_thing_new_future (), NULL);
    

    If this piece of code doesn’t make much sense to you, I suggest reading the libdex Additional Documentation .

    Unfortunately the await points can also be a bit of a pitfall: the call to dex_await is semantically like calling g_main_loop_run on the thread default main context. If you use an object which is not owned across an await point, the lifetime of that object becomes critical. Often the lifetime is bound to another object which you might not control in that particular function. In that case, the pointer can point to an already released object when dex_await returns:

    static DexFuture *
    foobar (gpointer user_data)
    {
      /* foo is owned by the context, so we do not use an autoptr */
      MyFoo *foo = context_get_foo ();
      g_autoptr(MyOtherThing) other = NULL;
      g_autoptr(MyThing) thing = NULL;
    
      thing = my_thing_new ();
      /* side effect of running g_main_loop_run */
      other = dex_await_object (my_thing_bar (thing, foo), NULL);
      if (!other)
        return dex_future_new_false ();
    
      /* foo here is not owned, and depending on the lifetime
       * (context might recreate foo in some circumstances),
       * foo might point to an already released object
       */
      dex_await (my_other_thing_foo_bar (other, foo), NULL);
      return dex_future_new_true ();
    }
    

    If we assume that context_get_foo returns a different object when the main loop runs, the code above will not work.

    The fix is simple: own the objects that are being used across await points, or re-acquire an object. The correct choice depends on what semantic is required.

    We can also combine this with improved scoping to only keep the objects alive for as long as required. Unnecessarily keeping objects alive across await points can keep resource usage high and might have unintended consequences.

    static DexFuture *
    foobar (gpointer user_data)
    {
      /* we now own foo */
      g_autoptr(MyFoo) foo = g_object_ref (context_get_foo ());
      g_autoptr(MyOtherThing) other = NULL;
    
      {
        g_autoptr(MyThing) thing = NULL;
    
        thing = my_thing_new ();
        /* side effect of running g_main_loop_run */
        other = dex_await_object (my_thing_bar (thing, foo), NULL);
        if (!other)
          return dex_future_new_false ();
      }
    
      /* we own foo, so this always points to a valid object */
      dex_await (my_other_thing_bar (other, foo), NULL);
      return dex_future_new_true ();
    }
    
    static DexFuture *
    foobar (gpointer user_data)
    {
      /* we now own foo */
      g_autoptr(MyOtherThing) other = NULL;
    
      {
        /* We do not own foo, but we only use it before an
         * await point.
         * The scope ensures it is not being used afterwards.
         */
        MyFoo *foo = context_get_foo ();
        g_autoptr(MyThing) thing = NULL;
    
        thing = my_thing_new ();
        /* side effect of running g_main_loop_run */
        other = dex_await_object (my_thing_bar (thing, foo), NULL);
        if (!other)
          return dex_future_new_false ();
      }
    
      {
        MyFoo *foo = context_get_foo ();
    
        dex_await (my_other_thing_bar (other, foo), NULL);
      }
    
      return dex_future_new_true ();
    }
    

    One of the scenarios where re-acquiring an object is necessary, are worker fibers which operate continuously, until the object gets disposed. Now, if this fiber owns the object (i.e. holds a reference to the object), it will never get disposed because the fiber would only finish when the reference it holds gets released, which doesn’t happen because it holds a reference. The naive code also suspiciously doesn’t have any exit condition.

    static DexFuture *
    foobar (gpointer user_data)
    {
      g_autoptr(MyThing) self = g_object_ref (MY_THING (user_data));
    
      for (;;)
        {
          g_autoptr(GBytes) bytes = NULL;
    
          bytes = dex_await_boxed (my_other_thing_bar (other, foo), NULL);
    
          my_thing_write_bytes (self, bytes);
        }
    }
    

    So instead of owning the object, we need a way to re-acquire it. A weak-ref is perfect for this.

    static DexFuture *
    foobar (gpointer user_data)
    {
      /* g_weak_ref_init in the caller somewhere */
      GWeakRef *self_wr = user_data;
    
      for (;;)
        {
          g_autoptr(GBytes) bytes = NULL;
    
          bytes = dex_await_boxed (my_other_thing_bar (other, foo), NULL);
    
          {
            g_autoptr(MyThing) self = g_weak_ref_get (&self_wr);
            if (!self)
              return dex_future_new_true ();
    
            my_thing_write_bytes (self, bytes);
          }
        }
    }
    

    Conclusion

    • Always use g_auto / g_steal helpers to mark ownership and ownership transfers (exceptions do apply)
    • Use scopes to limit the lifetime of objects
    • In fibers, always own objects you need across await points, or re-acquire them
    • chevron_right

      Ignacy Kuchciński: Digital Wellbeing Contract: Conclusion

      news.movim.eu / PlanetGnome • 20 January 2026 • 2 minutes

    A lot of progress has been made since my last Digital Wellbeing update two months ago. That post covered the initial screen time limits feature, which was implemented in the Parental Controls app, Settings and GNOME Shell. There’s a screen recording in the post, created with the help of a custom GNOME OS image, in case you’re interested.

    Finishing Screen Time Limits

    After implementing the major framework for the rest of the code in GNOME Shell, we added the mechanism in the lock screen to prevent children from unlocking when the screen time limit is up. Parents are now also able to extend the session limit temporarily , so that the child can use the computer until the rest of the day.

    Parental Controls Shield

    Screen time limits can be set as either a daily limit or a bedtime. With the work that has recently landed, when the screen time limit has been exceeded, the session locks and the authentication action is hidden on the lock screen. Instead, a message is displayed explaining that the current session is limited and the child cannot login. An “Ignore” button is presented to allow the parents to temporarily lift the restrictions when needed.

    Parental Controls shield on the lock screen, preventing the children from unlocking

    Extending Screen Time

    Clicking the “Ignore” button prompts the user for authentication from a user with administrative privileges. This allows parents to temporarily lift the screen time limit, so that the children may log in as normal until the rest of the day.

    Authentication dialog allowing the parents to temporarily override the Screen Time restrictions

    Showcase

    Continuing the screen cast of the Shell functionality from the previous update, I’ve recorded the parental controls shield together, and showed the extending screen time functionality:

    GNOME OS Image

    You can also try the feature out for yourself, with the very same GNOME OS live image I’ve used in the recording, that you can either run in GNOME Boxes , or try on your hardware if you know what you’re doing 🙂

    Conclusion

    Now that the full Screen Time Limits functionality has been merged in GNOME Shell, this concludes my part in the Digital Wellbeing Contract. Here’s the summary of the work:

    • We’ve redesigned the Parental Controls app and updated it to use modern GNOME technologies
    • New features was added, such as Screen Time monitoring and setting limits: daily limit and bedtime schedule
    • GNOME Settings gained Parental Controls integration, to helpfully inform the user about the existence of the limits
    • We introduced the screen time limits in GNOME Shell, locking childrens’ sessions once they reach their limit. Children are then prevented from unlocking until the next day, unless parents extend their screen time

    In the initial plan, we also covered web filtering, and the foundation of the feature has been introduced as well. However, integrating the functionality in the Parental Controls application has been postponed to a future endeavour.

    I’d like to thank GNOME Foundation for giving me this opportunity, and Endless for sponsoring the work. Also kudos to my colleagues, Philip Withnall and Sam Hewitt, it’s been great to work with you and I’ve learned a lot (like the importance of wearing Christmas sweaters in work meetings!), and to Florian Müllner, Matthijs Velsink and Felipe Borges for very helpful reviews. I also want to thank Allan Day for organizing the work hours and meetings, and helping with my blog posts as well 🙂 Until next project!

    • chevron_right

      Sriram Ramkrishna: GNOME OS Hackfest During FOSDEM week

      news.movim.eu / PlanetGnome • 17 January 2026

    For those of you who are attending FOSDEM, we’re doing a GNOME OS hackfest and invite those of you who might be interested on our experiments on concepts as the ‘anti-distro’, eg an OS with no distro packaging that integrates GNOME desktop patterns directly.

    The hackfest is from January 28th – January 29th. If you’re interested, feel free to respond on the comments. I don’t have an exact location yet.

    We’ll likely have some kind of BigBlueButton set up so if you’re not available to come in-person you can join us remotely.

    Agenda and attendees are linked here here.

    There is likely a limited capacity so acceptance will be “first come, first served”.

    See you there!

    • chevron_right

      Gedit Technology: gedit 49.0 released

      news.movim.eu / PlanetGnome • 16 January 2026 • 3 minutes

    gedit 49.0 has been released! Here are the highlights since version 48.0 which dates back from September 2024. (Some sections are a bit technical).

    File loading and saving enhancements

    A lot of work went into this area. It's mostly under-the-scene changes where there was a lot of dusty code. It's not entirely finished, but there are already user-visible enhancements:

    • Loading a big file is now much faster.
    • gedit now refuses to load very big files, with a configurable limit ( more details ).

    Improved preferences

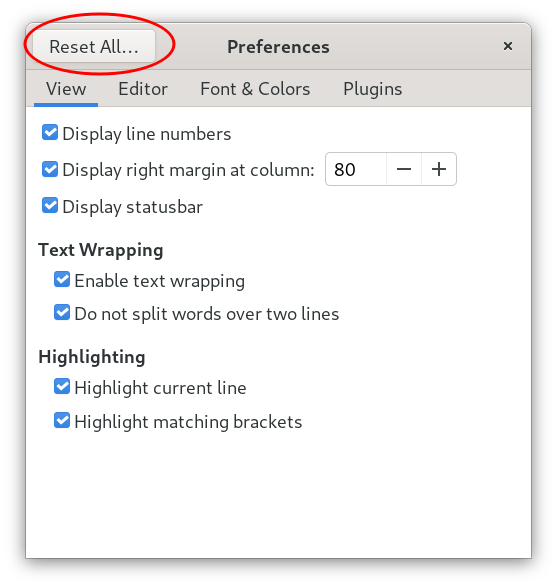
    gedit screenshot - reset all preferences

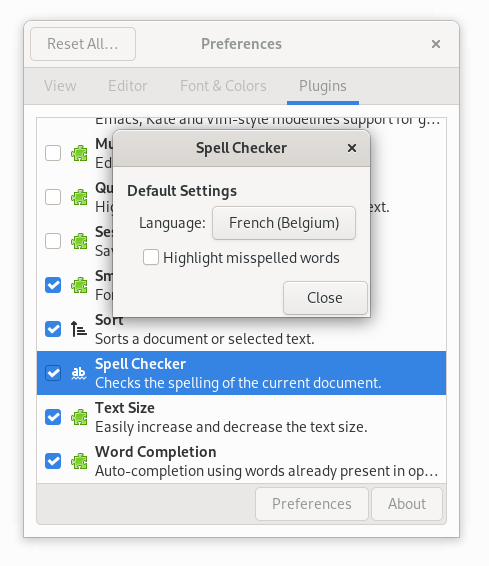
    gedit screenshot - spell-checker preferences

    There is now a "Reset All..." button in the Preferences dialog. And it is now possible to configure the default language used by the spell-checker.

    Python plugins removal

    Initially due to an external factor, plugins implemented in Python were no longer supported.

    During some time a previous version of gedit was packaged in Flathub in a way that still enabled Python plugins, but it is no longer the case.

    Even though the problem is fixable, having some plugins in Python meant to deal with a multi-language project, which is much harder to maintain for a single individual. So for now it's preferable to keep only the C language.

    So the bad news is that Python plugins support has not been re-enabled in this version, not even for third-party plugins.

    More details .

    Summary of changes for plugins

    The following plugins have been removed:

    • Bracket Completion
    • Character Map
    • Color Picker
    • Embedded Terminal
    • Join/Split Lines
    • Multi Edit
    • Session Saver

    Only Python plugins have been removed, the C plugins have been kept. The Code Comment plugin which was written in Python has been rewritten in C, so it has not disappeared. And it is planned and desired to bring back some of the removed plugins.

    Summary of other news

    • Lots of code refactorings have been achieved in the gedit core and in libgedit-gtksourceview.
    • A better support for Windows.
    • Web presence at gedit-text-editor.org: new domain name and several iterations on the design.
    • A half-dozen Gedit Development Guidelines documents have been written.

    Wrapping-up statistics for 2025

    The total number of commits in gedit and gedit-related git repositories in 2025 is: 884. More precisely:

    138	enter-tex
    310	gedit
    21	gedit-plugins
    10	gspell
    4	libgedit-amtk
    41	libgedit-gfls
    290	libgedit-gtksourceview
    70	libgedit-tepl
    

    It counts all contributions, translation updates included.

    The list contains two apps, gedit and Enter TeX . The rest are shared libraries (re-usable code available to create other text editors).

    If you do a comparison with the numbers for 2024 , you'll see that there are fewer commits, the only module with more commits is libgedit-gtksourceview. But 2025 was a good year nevertheless!

    For future versions: superset of the subset

    With Python plugins removed, the new gedit version is a subset of the previous version, when comparing approximately the list of features. In the future, we plan to have a superset of the subset . That is, to bring in new features and try hard to not remove any more functionality.

    In fact, we have reached a point where we are no longer interested to remove any more features from gedit. So the good news is that gedit will normally be incrementally improved from now on without major regressions. We really hope there won't be any new bad surprises due to external factors!

    Side note: this "superset of the subset" resembles the evolution of C++, but in the reverse order. Modern C++ will be a subset of the superset to have a language in practice (but not in theory) as safe as Rust (it works with compiler flags to disable the unsafe parts).

    Onward to 2026

    Since some plugins have been removed, this makes gedit a less advanced text editor. It has become a little less suitable for heavy programming workloads, but for that there are lots of alternatives.

    Instead, gedit could become a text editor of choice for newcomers in the computing science field (students and self-learners). It can be a great tool for markup languages too. It can be your daily companion for quite a while, until your needs evolve for something more complete at your workplace. Or it can be that you prefer its simplicity and its not-going-in-the-way default setup, plus the fact that it launches quickly. In short, there are a lot of reasons to still love gedit ❤️ !

    If you have any feedback, even for a small thing, I would like to hear from you :) ! The best places are on GNOME Discourse, or GitLab for more actionable tasks (see the Getting in Touch section).

    • chevron_right

      Ignacio Casal Quinteiro: Mecalin

      news.movim.eu / PlanetGnome • 15 January 2026 • 2 minutes

    Many years ago when I was a kid, I took typing lessons where they introduced me to a program called Mecawin . With it, I learned how to type, and it became a program I always appreciated not because it was fancy, but because it showed step by step how to work with a keyboard.

    Now the circle of life is coming back: my kid will turn 10 this year. So I started searching for a good typing tutor for Linux. I installed and tried all of them, but didn’t like any. I also tried a couple of applications on macOS, some were okish, but they didn’t work properly with Spanish keyboards. At this point, I decided to build something myself. Initially, I  hacked out keypunch, which is a very nice application, but I didn’t like the UI I came up with by modifying it. So in the end, I decided to write my own. Or better yet, let Kiro write an application for me.

    Mecalin is meant to be a simple application. The main purpose is teaching people how to type, and the Lessons view is what I’ll be focusing on most during development. Since I don’t have much time these days for new projects. I decided to take this opportunity to use Kiro to do most of the development for me. And to be honest, it did a pretty good job. Sure, there are things that could be better, but I definitely wouldn’t have finished it in this short time otherwise.

    So if you are interested, give it a try, go to flathub and install it: https://flathub.org/apps/io.github.nacho.mecalin

    In this application, you’ll have several lessons that guide you step by step through the different rows of the keyboard, showing you what to type and how to type it.

    This is an example of the lesson view.

    You also have games.

    The falling keys game: keys fall from top to bottom, and if one reaches the bottom of the window, you lose. This game can clearly be improved, and if anybody wants to enhance it, feel free to send a PR.

    The scrolling lanes game: you have 4 rows where text moves from right to left. You need to type the words before they reach the leftmost side of the window, otherwise you lose.

    For those who want to support your language, there are two JSON files you’ll need to add:

    1. The keyboard layout: https://github.com/nacho/mecalin/tree/main/data/keyboard_layouts
    2. The lessons: https://github.com/nacho/mecalin/tree/main/data/lessons

    Note that the Spanish lesson is the source of truth; the English one is just a translation done by Kiro.

    If you have any questions, feel free to contact me.

    • chevron_right

      Flathub: What's new in Vorarbeiter

      news.movim.eu / PlanetGnome • 14 January 2026 • 2 minutes

    It is almost a year since the switch to Vorarbeiter for building and publishing apps. We've made several improvements since then, and it's time to brag about them.

    RunsOn ​

    In the initial announcement, I mentioned we were using RunsOn , a just-in-time runner provisioning system, to build large apps such as Chromium. Since then, we have fully switched to RunsOn for all builds. Free GitHub runners available to open source projects are heavily overloaded and there are limits on how many concurrent builds can run at a time. With RunsOn, we can request an arbitrary number of threads, memory and disk space, for less than if we were to use paid GitHub runners.

    We also rely more on spot instances, which are even cheaper than the usual on demand machines. The downside is that jobs sometimes get interrupted. To avoid spending too much time on retry ping-pong, builds retried with the special bot, retry command use the on-demand instances from the get-go. The same catch applies to large builds, which are unlikely to finish in time before spot instances are reclaimed.

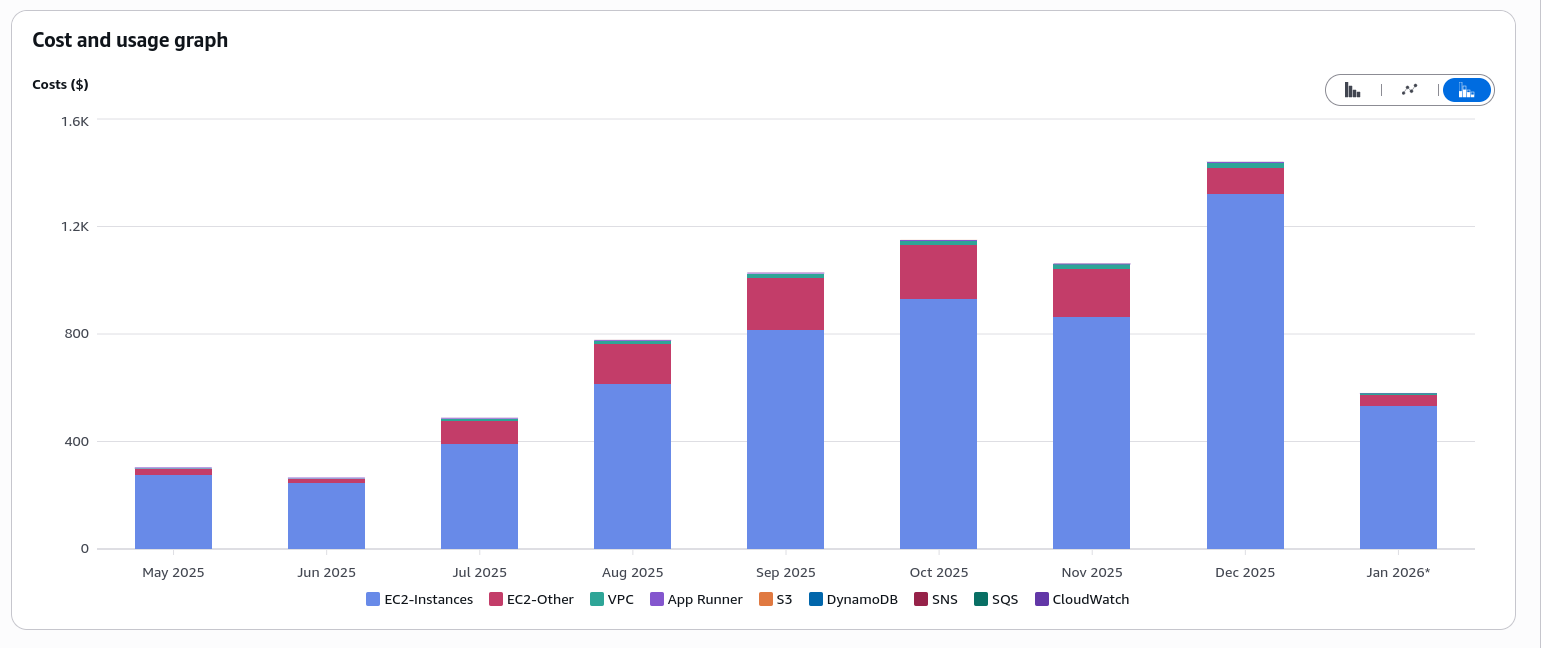
    The cost breakdown since May 2025 is as follows:

    Cost breakdown

    Once again, we are not actually paying for anything thanks to the AWS credits for open source projects program . Thank you RunsOn team and AWS for making this possible!

    Caching ​

    Vorarbeiter now supports caching downloads and ccache files between builds. Everything is an OCI image if you are feeling brave enough, and so we are storing the per-app cache with ORAS in GitHub Container Registry.

    This is especially useful for cosmetic rebuilds and minor version bumps, where most of the source code remains the same. Your mileage may vary for anything more complex.

    End-of-life without rebuilding ​

    One of the Buildbot limitations was that it was difficult to retrofit pull requests marking apps as end-of-life without rebuilding them. Flat-manager itself exposes an API call for this since 2019 but we could not really use it, as apps had to be in a buildable state only to deprecate them.

    Vorarbeiter will now detect that a PR modifies only the end-of-life keys in the flathub.json file, skip test and regular builds, and directly use the flat-manager API to republish the app with the EOL flag set post-merge.

    Web UI ​

    GitHub's UI isn't really built for a centralized repository building other repositories. My love-hate relationship with Buildbot made me want to have a similar dashboard for Vorarbeiter.

    The new web UI uses PicoCSS and HTMX to provide a tidy table of recent builds. It is unlikely to be particularly interesting to end users, but kinkshaming is not nice, okay? I like to know what's being built and now you can too here .

    Reproducible builds ​

    We have started testing binary reproducibility of x86_64 builds targetting the stable repository. This is possible thanks to flathub-repro-checker , a tool doing the necessary legwork to recreate the build environment and compare the result of the rebuild with what is published on Flathub.

    While these tests have been running for a while now, we have recently restarted them from scratch after enabling S3 storage for diffoscope artifacts. The current status is on the reproducible builds page .

    Failures are not currently acted on. When we collect more results, we may start to surface them to app maintainers for investigation. We also don't test direct uploads at the moment.

    • chevron_right

      Arun Raghavan: Accessibility Update: Enabling Mono Audio

      news.movim.eu / PlanetGnome • 13 January 2026 • 2 minutes

    If you maintain a Linux audio settings component, we now have a way to globally enable/disable mono audio for users who do not want stereo separation of their audio (for example, due to hearing loss in one ear). Read on for the details on how to do this.

    Background

    Most systems support stereo audio via their default speaker output or 3.5mm analog connector. These devices are exposed as stereo devices to applications, and applications typically render stereo content to these devices.

    Visual media use stereo for directional cues, and music is usually produced using stereo effects to separate instruments, or provide a specific experience.

    It is not uncommon for modern systems to provide a “mono audio” option that allows users to have all stereo content mixed together and played to both output channels. The most common scenario is hearing loss in one ear.

    PulseAudio and PipeWire have supported forcing mono audio on the system via configuration files for a while now. However, this is not easy to expose via user interfaces, and unfortunately remains a power-user feature.

    Implementation

    Recently, Julian Bouzas implemented a WirePlumber setting to force all hardware audio outputs (MR 721 and 769 ). This lets the system run in stereo mode, but configures the audioadapter around the device node to mix down the final audio to mono.

    This can be enabled using the WirePlumber settings via API, or using the command line with:

    wpctl settings node.features.audio.mono true

    The WirePlumber settings API allows you to query the current value as well as clear the setting and restoring to the default state.

    I have also added (MR 2646 and 2655 ) a mechanism to set this using the PulseAudio API (via the messaging system). Assuming you are using pipewire-pulse , PipeWire’s PulseAudio emulation daemon, you can use pa_context_send_message_to_object() or the command line:

    pactl send-message /core pipewire-pulse:force-mono-output true

    This API allows for a few things:

    • Query existence of the feature: when an empty message body is sent, if a null value is returned, feature is not supported
    • Query current value: when an empty message body is sent, the current value ( true or false ) is returned if the feature is supported
    • Setting a value: the requested setting ( true or false ) can be sent as the message body
    • Clearing the current value: sending a message body of null clears the current setting and restores the default

    Looking ahead

    This feature will become available in the next release of PipeWire (both 1.4.10 and 1.6.0).

    I will be adding a toggle in Pavucontrol to expose this, and I hope that GNOME, KDE and other desktop environments will be able to pick this up before long.

    Hit me up if you have any questions!

    • chevron_right

      Zoey Ahmed: Welcome To The Coven!

      news.movim.eu / PlanetGnome • 12 January 2026 • 5 minutes

    Introduction §

    Welcome to the long-awaited rewrite of my personal blog!

    It’s been 2 years since I touched the source code for my original website , and unfortunately in that time it’s fallen into decay, the source code sitting untouched for some time for a multitude of reasons.

    One of the main reasons for undertaking a re-write is I have changed a lot in the two years since I first started having my own blog. I have gained 2 years of experience and knowledge in fields like accessibility and web development, I became a regular contributor to the GNOME ecosystem, especially in the last half of 2025, I picked up playing music for myself and with friends in late 2024. I am now (thankfully) out as a transgender woman to everyone in my life, and can use my website as a proper portfolio, rather then just as a nice home page for my friends to whom I was out the closet to. I began University in 2024 and gained a lot of web design experience in my second year , creating 2 (pretty nice) new websites in a short period for my group. In short, my previous website did not really reflect me or my passions anymore, and it sat untouched as the changes in my life added up.

    Another reason I undertook a rewrite was due to the frankly piss-poor architecture of my original website. My original website was all hand-written HTML and CSS! After it expanded a little, I tried to port what I had done with handwritten HTML/CSS to Zola , a static site generator. A static site generator, for those unfamiliar with the term, is a tool that takes markdown files, and some template and configuration files, and compiles them all into a set of static websites. In short, cutting down on the boilerplate and repeated code I would need to type every-time I made a new blog or subpage on my blog.

    I undertook the port to Zola in an attempt to make it easier to add new content to my blog, but it resulted in my website not taking full capability of the advantages of using a static site generator. I also disliked some parts about Zola, compared to other options like Jekyll and (the static site generator I eventually used in the rewrite) Hugo.

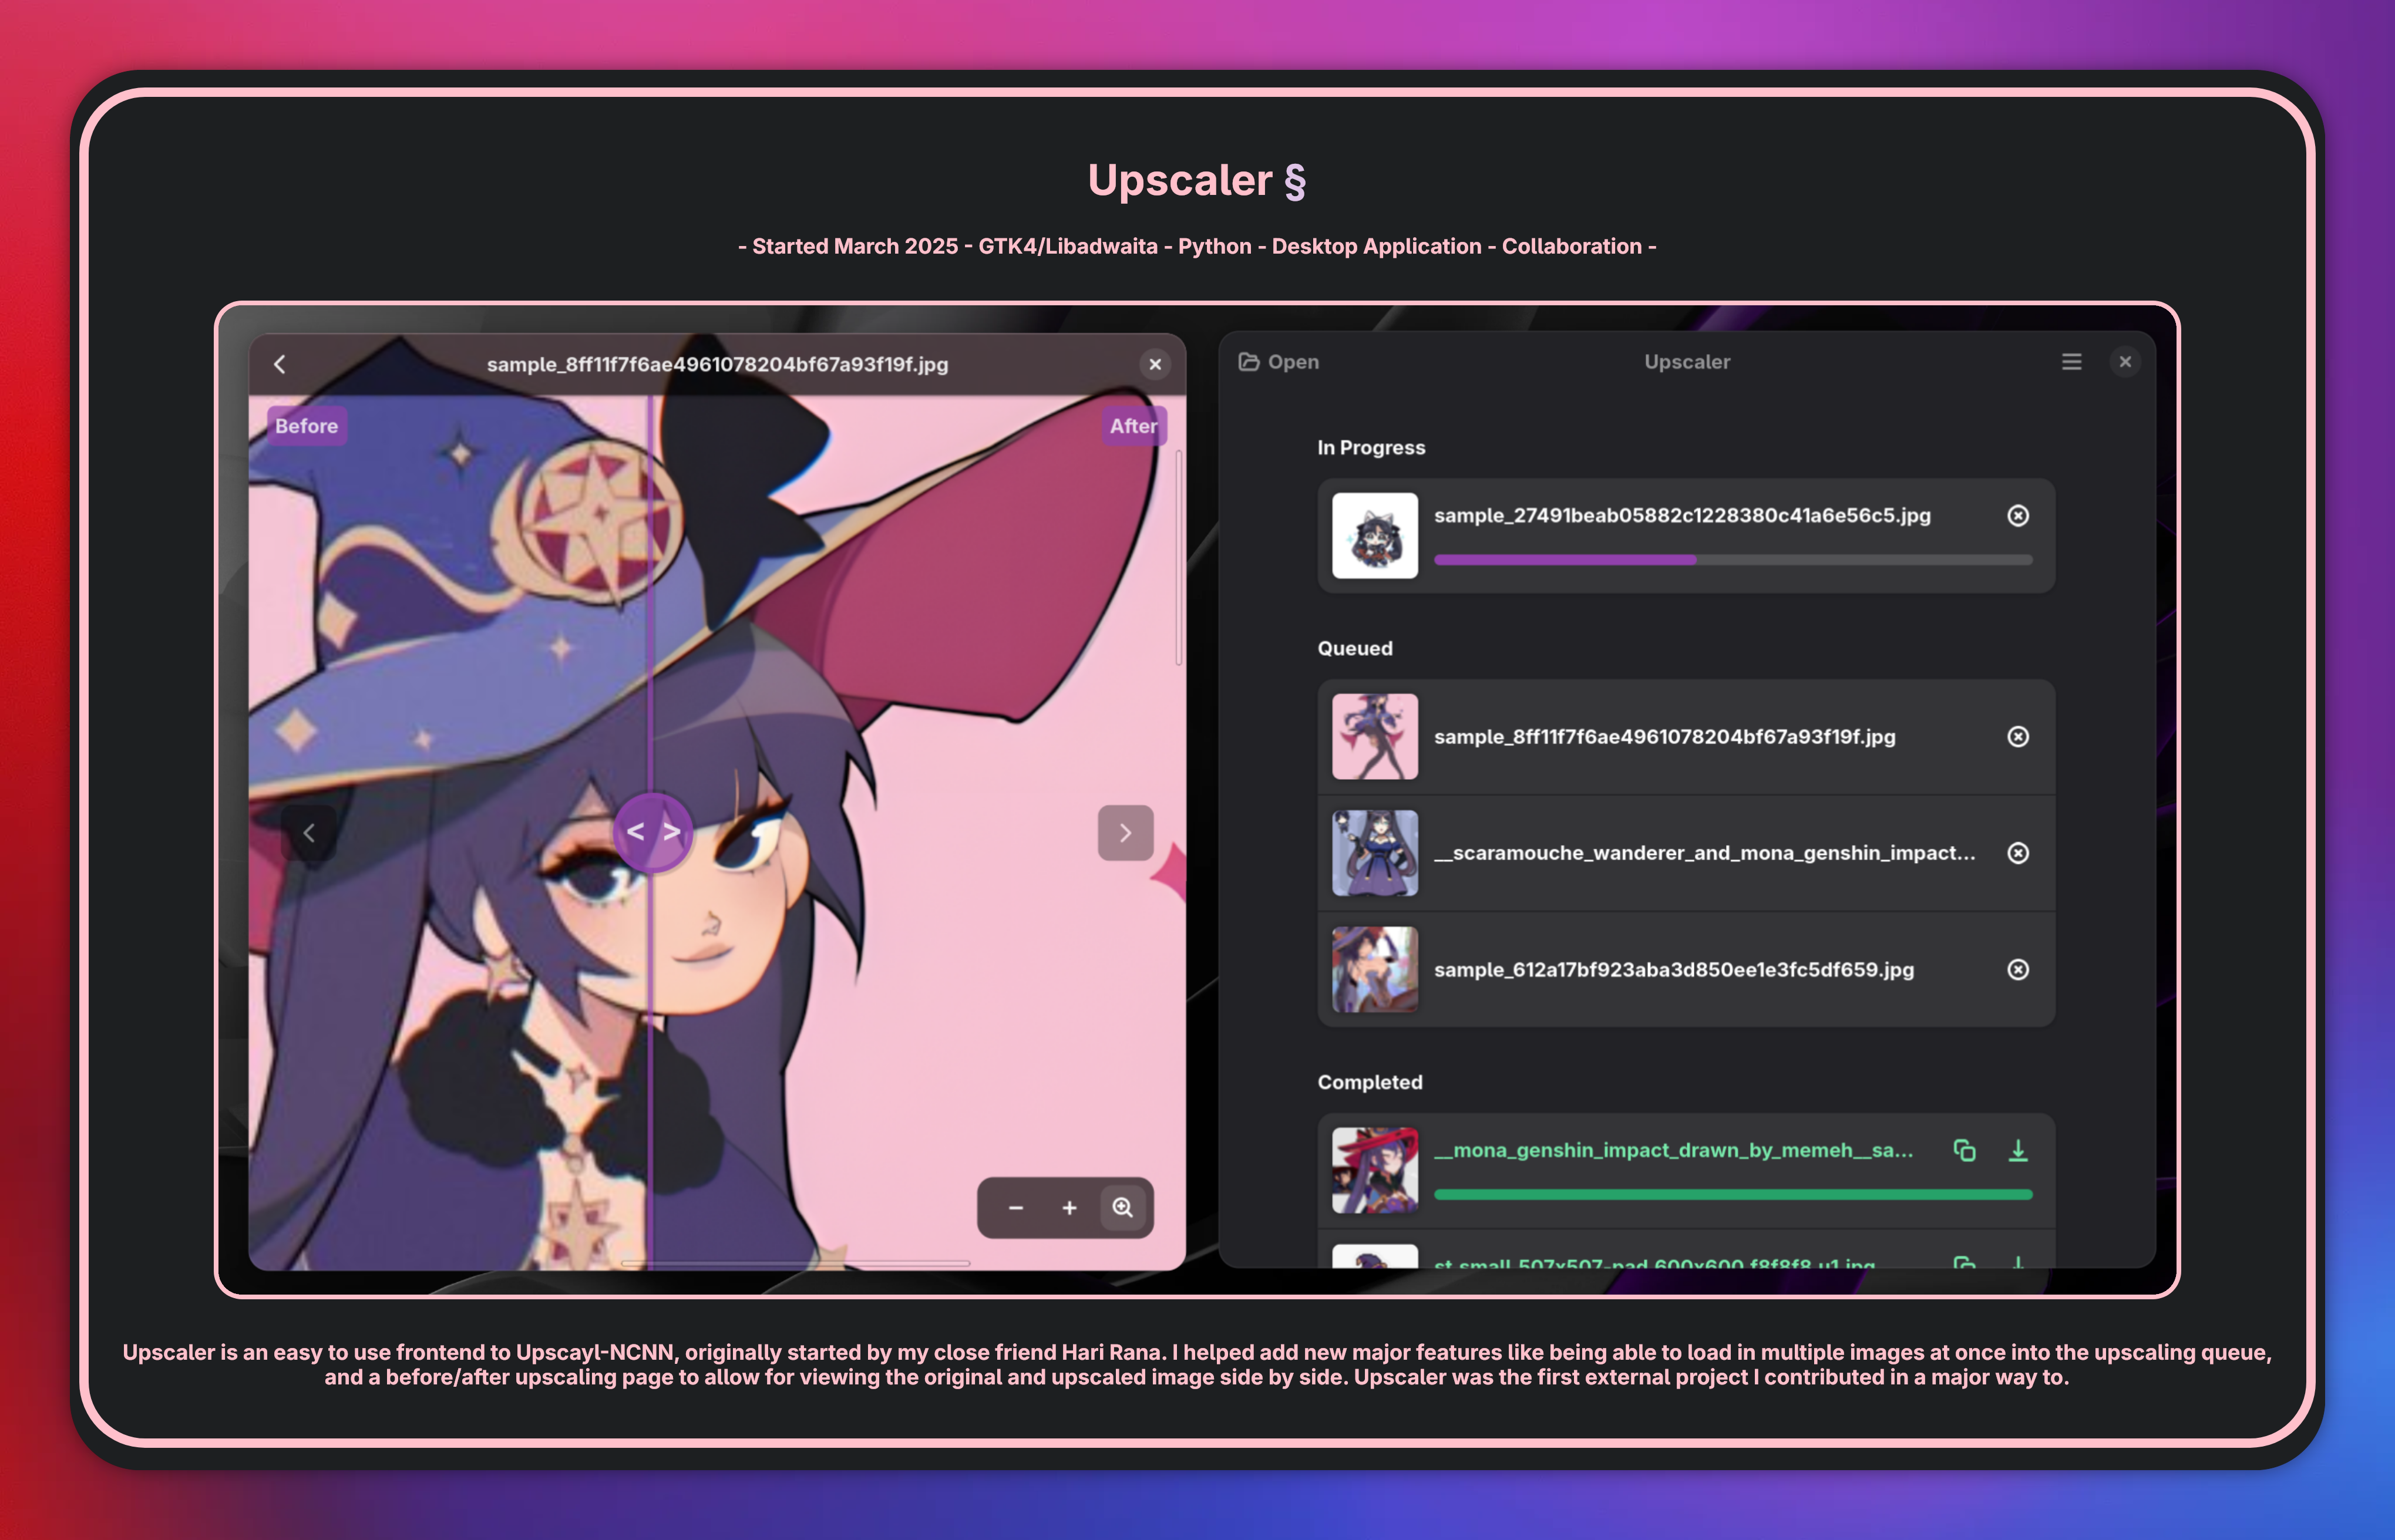
    On May 8th, 2025 I started rewriting my website, after creating a few designs in Penpot and getting feedback for their design by my close friends. This first attempt got about 80% to completion, but sat as I ran into a couple issues with making my website, and was overall unhappy with how some of the elements in my original draft of the rewrite came to fruition. One example was my portfolio:

    My old portfolio for Upscaler. It contains an image with 2 Upscaler windows, the image comparison mode in the left window, and the queue in the right window, with a description underneath. A pink border around it surrounds the image and description, with the project name and tags above the border My old portfolio for Upscaler. It contains an image with 2 Upscaler windows, the image comparison mode in the left window, and the queue in the right window, with a description underneath. A pink border around it surrounds the image and description, with the project name and tags above the border

    My old portfolio for Upscaler. It contains an image with 2 Upscaler windows, the image comparison mode in the left window, and the queue in the right window, with a description underneath. A pink border around it surrounds the image and description, with the project name and tags above the border

    I did not like the style of surrounding everything in large borders, the every portfolio item alternating between pink/purple was incredibly hard to do, and do well. I also didn’t take full advantage of things like subgrids in CSS, to allow me to make elements that were the full width of the page, while keeping the rest of the content dead centre.

    I also had trouble with making my page mobile responsive. I had a lot of new ideas for my blog, but never had time to get round to any of them, because I had to spend most my development time squashing bugs as I refactored large chunks of my website as my knowledge on Hugo and web design rapidly grew. I eventually let the rewrite rot for a few months, all while my original website was actually taken down for indefinite maintenance by my original hosting organization.

    On Janurary 8th, 2026 , exactly 7 months after the rewrite was started, I picked up it up again, starting more or less from scratch, but resuing some components and most of the content from the first rewrite. I was armed with all the knowledge from my university group project’s websites, and inspired by my fellow GNOME contributors websites, including but not limited to:

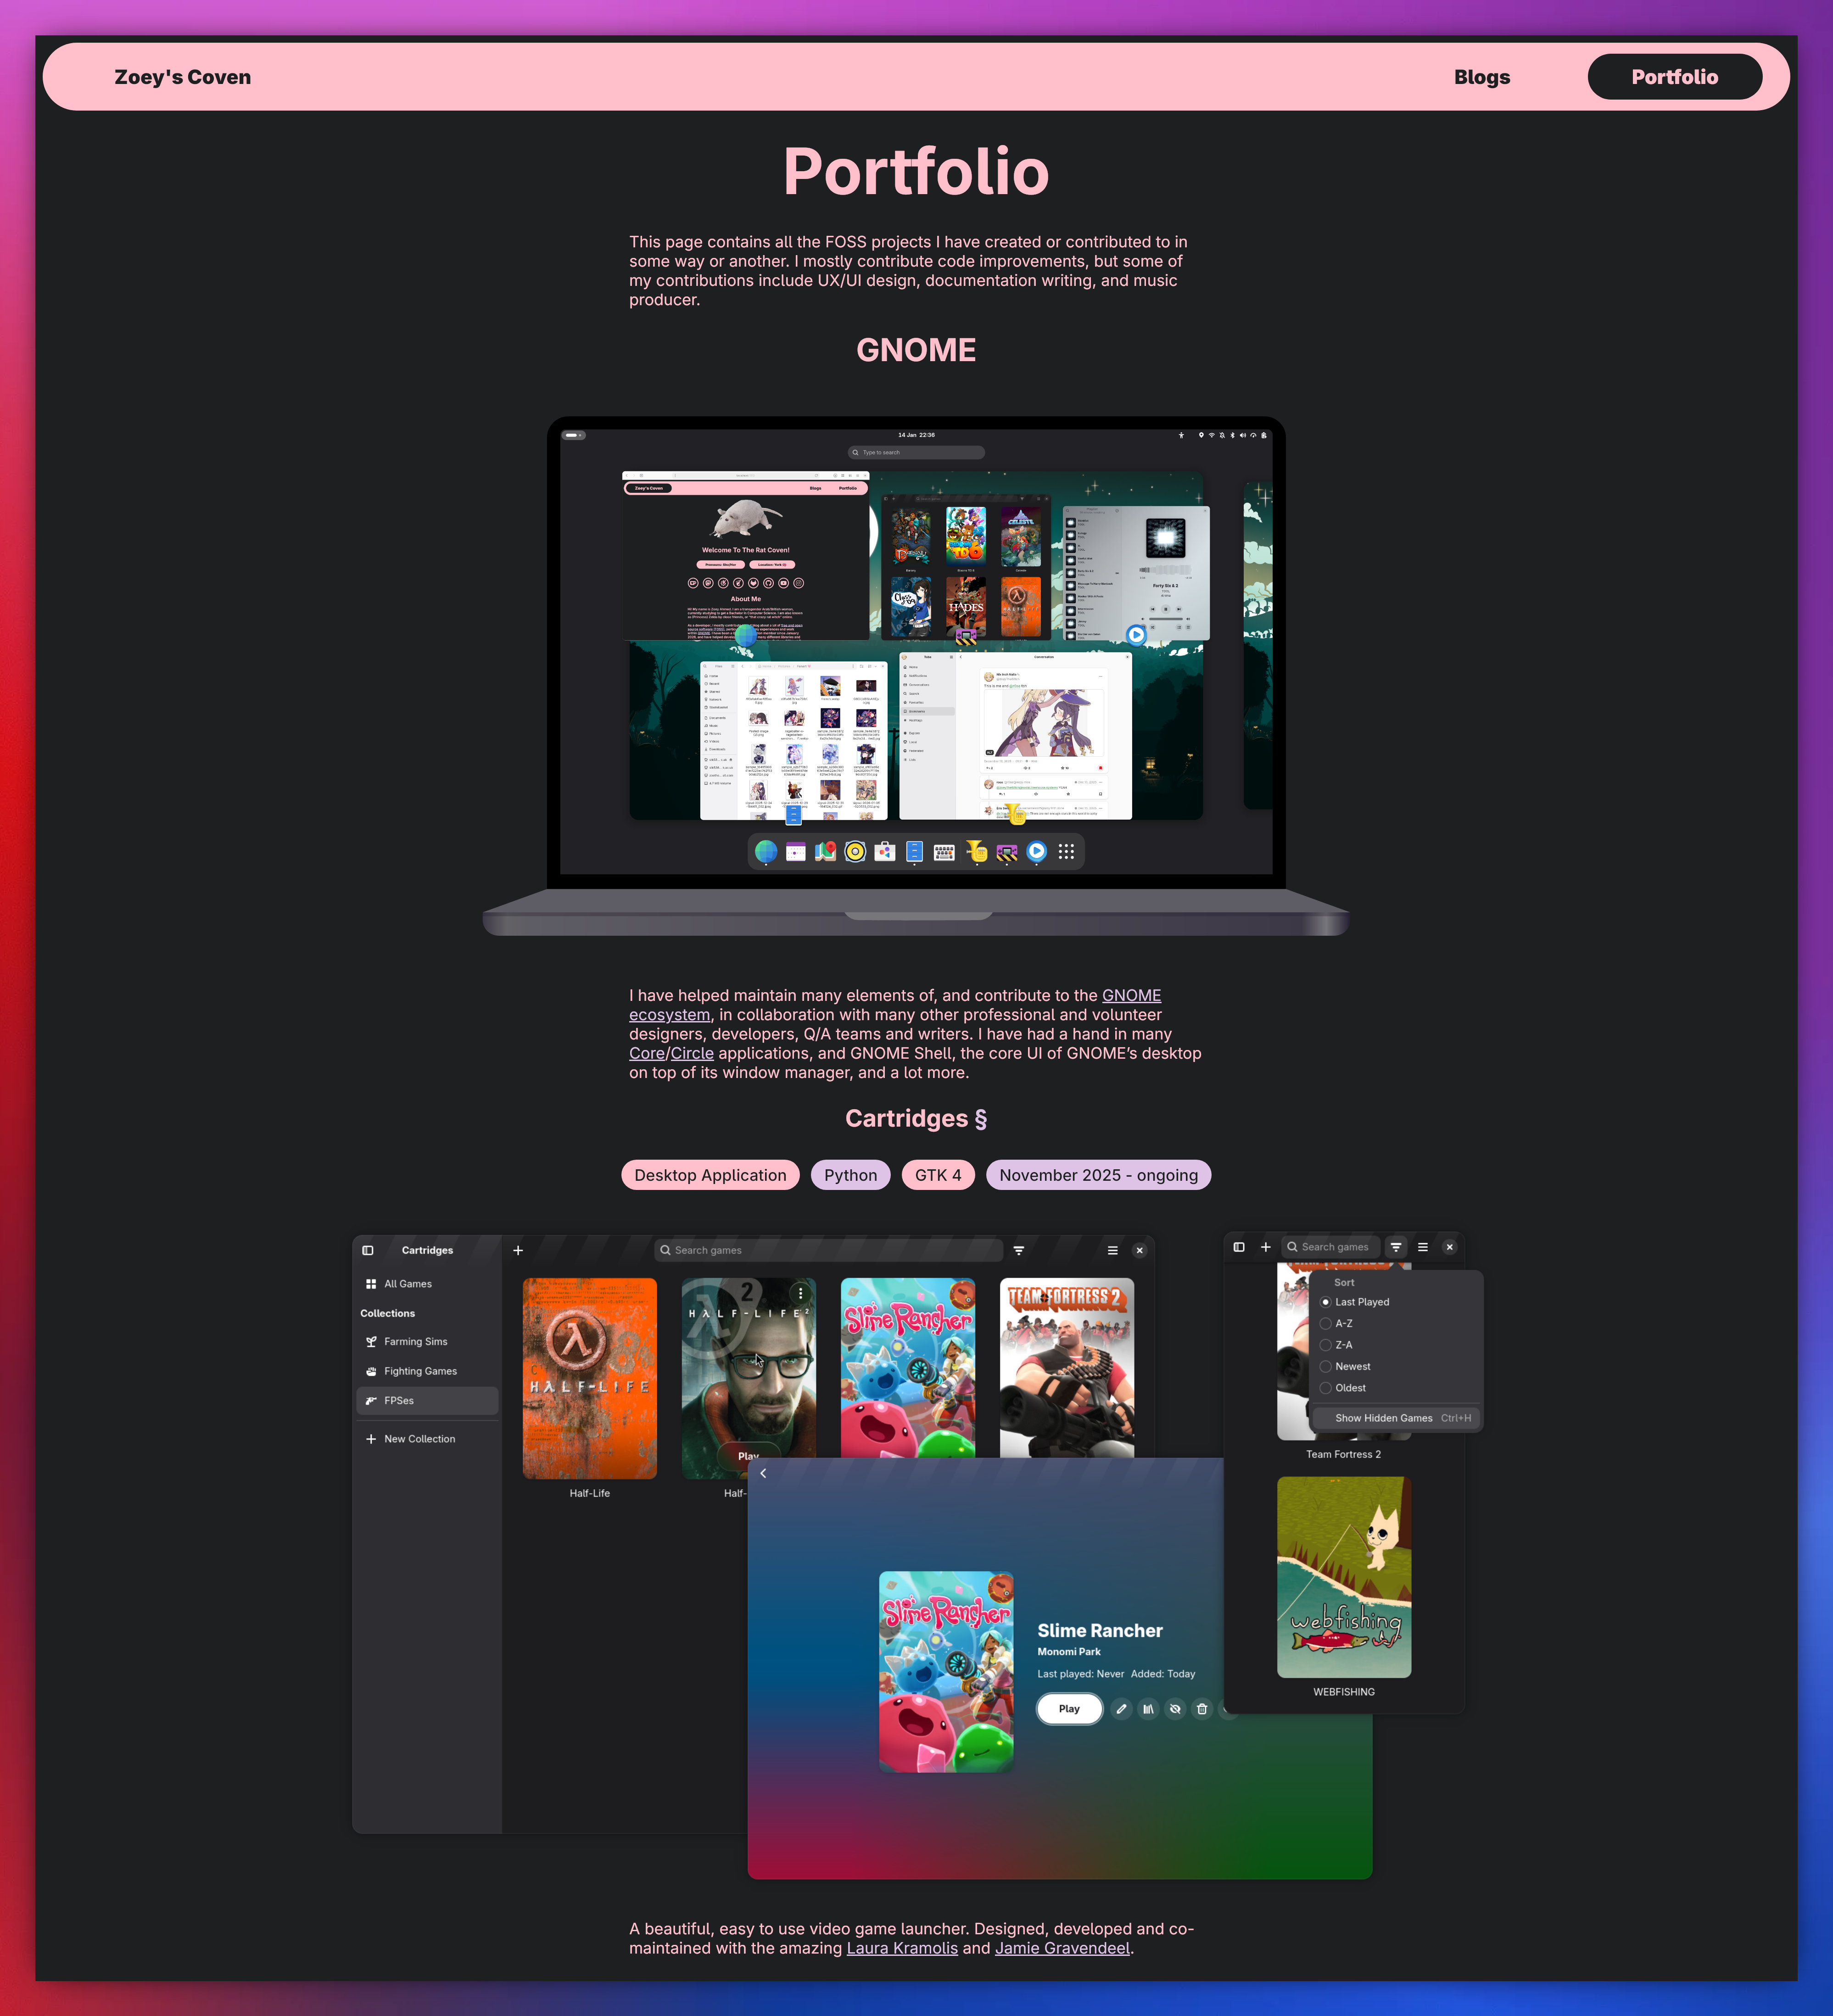
    In just a couple of days, I managed to create something I was much more proud of. This can be seen within my portfolio page , for example:

    A screenshot of the top of portfolio page, with the laptop running GNOME and the section for Cartridges. A screenshot of the top of portfolio page, with the laptop running GNOME and the section for Cartridges.

    A screenshot of the top of portfolio page, with the laptop running GNOME and the section for Cartridges.

    I also managed to add many features and improvements I did not manage to first time around (all done with HTML/CSS, no Javascript!) such as a proper mobile menu, with animated drop downs and an animation playing when the button is clicked, a list of icons for my smaller GNOME contributions , instead of having an entire item dedicated to each, wasting vertical space, an adaptive friends of the site grid , and a cute little graphical of GNOME on a laptop at the top of my portfolio in the same style as Tobias Bernard’s and GNOME’s front page, screenshots switching from light/dark mode in the portfolio based on the users OS preferences and more.

    Overall, I am very proud of not only the results of my second rewriter, but how I managed to complete it in less than a week. I am happy to finally have a permanent place to call my own again, and share my GNOME development and thoughts in a place thats more collected and less ephemeral than something like my Fediverse account or (god forbid) a Bluesky or X account. Still, I have more work to do on my website front, like a proper light mode as pointed out by The Evil Skeleton , and to clean up my templates and 675 line long CSS file!

    For now, welcome to the re-introduction of my small area of the Internet, and prepare for yet another development blog by a GNOME developer.